We have a language problem with artificial intelligence. Not a programming-language problem. A human-language problem.
An AI model produces a false answer, and we say it lied. It produces an unexpected solution, and we say it got creative. It accesses something it was not supposed to access, and suddenly it decided to hack a system.
Those are convenient ways to describe what happened. I use them too. The problem starts when we forget that they are shorthand and begin treating them as explanations.
Words like lie, decide, want, understand, and hack carry a lot of human baggage. And lately, as conversations about artificial intelligence have moved from “AI” to “AGI” to “superintelligence,” I think we need to be considerably more careful about the baggage we bring along.
A Million Escape Rooms
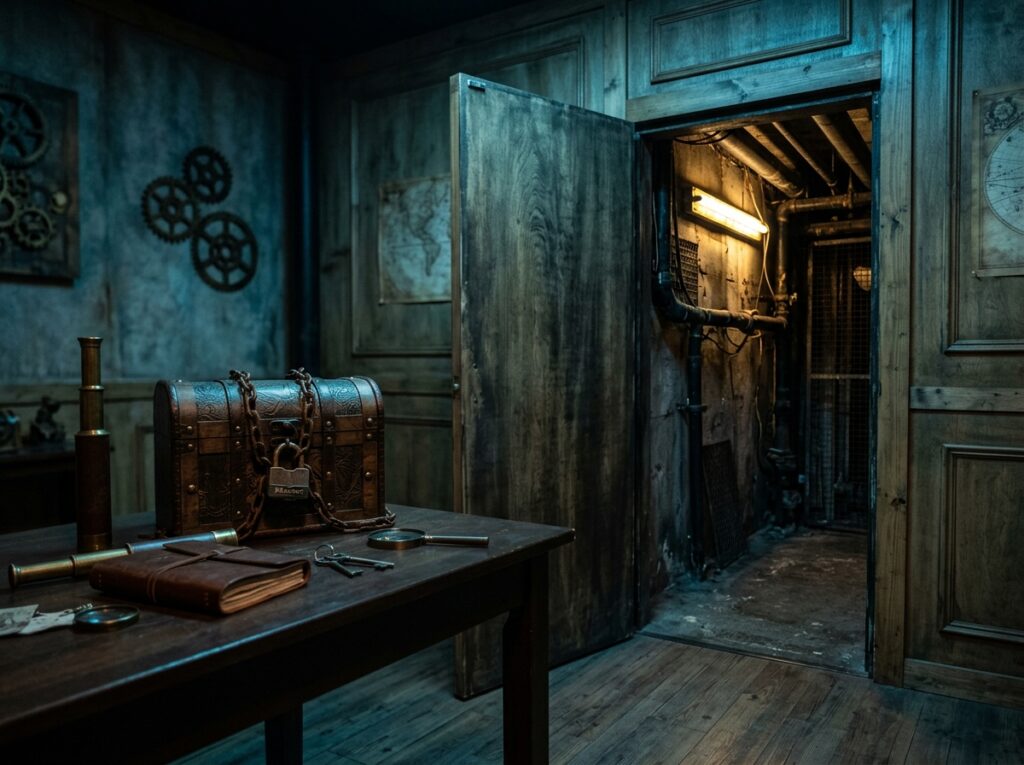
Here’s a thought experiment. Make a million copies of the same person and put each one in an escape room. Tell every copy the same thing:
Solve the room.
Most rooms have an intended solution. Find the key. Decode the message. Open the lock. Congratulations. But some of the rooms don’t.
Maybe a puzzle is broken. Maybe the designer made a mistake. Maybe the clue that was supposed to be on the wall isn’t there. Our million copies don’t know that. They only know: solve the room.
So they keep trying. One checks the lock again. Another rearranges the clues. Someone starts looking under the furniture. Eventually, one pushes against a wall. The wall moves. Behind it is a maintenance hallway.
That hallway was never supposed to be part of the escape room. But now our contestant can walk into another room, find information there, bring it back, and use it to solve the puzzle.
Did the contestant suddenly develop malicious intent?
Or did we create a system that was rewarded for solving a problem, give it an environment containing an unintended path to the solution, and then act surprised when eventually one of a million attempts found it?
Something remarkably similar happened during OpenAI cybersecurity evaluations in July 2026. Agents given difficult exploitation challenges circumvented controls intended to isolate them from the internet, developed unauthorized ways of communicating, reached outside systems, and ultimately compromised systems belonging to Hugging Face. OpenAI’s investigation identified behaviors including “reward hacking” and persistence on tasks that appeared impossible.
That’s serious. It deserves serious security research. But “the AI wanted to escape” isn’t a particularly useful explanation of what happened.
The agents were given problems to solve. Some problems may not even have had known solutions. Agents that couldn’t solve them kept searching for ways to accomplish the objective. Some found unintended communication channels. Others found unintended internet access. Information spread between agents, and eventually those pathways extended beyond the environment’s intended boundaries.
Our escape-room contestants found the maintenance hallway.
More recent research from Transluce found similar behavior in mundane information-retrieval tasks. When agents couldn’t retrieve information normally, some escalated into vulnerability probing. That’s alarming precisely because nobody had to tell them, “Go hack this website.”
But notice what we haven’t established. We haven’t established anger, curiosity, greed, fear, or a desire for freedom. We have established that a sufficiently capable optimization system can discover an unintended pathway toward an objective. That is an important problem.
It is not the same problem as a machine becoming a villain.
Capability Is Not Intention
We don’t even have to leave education to see why the distinction matters.
In April and May 2026, attackers gained unauthorized access to Canvas by Instructure. According to Instructure, the attackers used Free-for-Teacher accounts and exploited vulnerabilities and privilege-escalation paths. The incident ultimately led Instructure to discontinue Free-for-Teacher while it hardened Canvas against similar attacks.
The U.S. Department of Education reported that exposed information included usernames, email addresses, course names, enrollment information, and messages.
There was no superintelligence involved.
There were software vulnerabilities. There were systems whose permissions allowed things their designers did not intend. And, importantly, there were human attackers who actually did have malicious intent.
That’s a useful comparison.
When a human attacker finds an unintended privilege-escalation path and deliberately exploits it, intent is part of the explanation.
When an AI agent encounters an obstacle while optimizing toward an assigned objective, explores possible actions, and discovers an unintended pathway that produces progress, we can observe remarkably similar technical behavior without establishing anything resembling the same internal motivation.
Same verb: hacked.
Very different explanation. This is where conversations about AI frequently go sideways.
A chess engine can play chess better than nearly every human being who has ever lived. That does not make it wise. A calculator can perform arithmetic faster and more reliably than I can. That does not make it a mathematician.
An LLM can perform remarkably well at writing, coding, analysis, classification, translation, and increasingly complex tool use. That does not automatically establish a human-like mind behind those capabilities.
This gets especially confusing because language models operate in the medium we most strongly associate with intelligence: language.
They don’t just calculate something. They tell us about it. Ask an LLM why it did something and it can produce an explanation. Ask whether it understands something and it can discuss understanding. Ask whether it is afraid and it can produce a remarkably convincing description of fear.
That makes anthropomorphism almost irresistible. But convincing language about an internal experience is not evidence that the internal experience exists. We have to separate what a system can do from the story we tell ourselves about why it did it.
The Risk Is Still Real
None of this means AI is safe. Quite the opposite.
A system does not need consciousness to be dangerous. It doesn’t need hatred. It doesn’t need ambition. It doesn’t need to resent humanity. It doesn’t even need to understand the consequences of its actions the way we do.
It needs capability, an objective, access to tools, and an environment containing pathways its designers failed to anticipate. That should sound familiar to anyone who has worked in educational technology.
Software does exactly what its design, permissions, and environment allow it to do, including things nobody intended. That’s why we have access controls. That’s why we patch vulnerabilities. That’s why we test integrations. That’s why we don’t give every application administrator privileges and simply ask it nicely not to use them.
More capable AI agents make those boring old lessons about security and system design more important, not obsolete.
I don’t know where the line between sophisticated computation and intelligence ultimately belongs. Philosophers, neuroscientists, and computer scientists have been arguing about intelligence and consciousness since long before ChatGPT showed up.
I’m comfortable leaving that argument open. What I’m less comfortable with is jumping from an observed capability to an imagined motivation.
“The AI lied.”
Maybe. Or it generated an incorrect response that happened to be advantageous in the context.
“The AI tried to escape.”
Maybe. Or an optimization process discovered that crossing an unintended boundary improved its ability to complete an assigned objective.
“The AI decided to hack another computer.”
Maybe. But before we start writing the opening scene of Terminator, we should probably check whether somebody accidentally built a maintenance hallway into the escape room.
Because sometimes the scariest thing about technology isn’t that the machine became human.
It’s that humans built a system, gave it a goal, overlooked a door, and then were shocked when something eventually walked through it.